|
I am a final-year PhD student at Johns Hopkins University, where I am fortunate to be advised by Bloomberg Distinguished Professor Alan L. Yuille. Before that I was an M.S. student at Tsinghua University, where I worked under the guidance of Prof. Hairong Lv. I also spent wonderful time interning at Google Research, ByteDance Seed, Microsoft Research, and UIUC. My research focuses on video world models and unified vision-language systems. I am on the job market this year. Please feel free to reach out! |
|
|
[2026.09] 4 papers accepted by NeurIPS 2026. An interesting finding: video editing can be done by image editors! [2026.07] RINO is released: unified VLMs (i.e., image editors) can handle nearly all vision tasks by representing all visual information in RGB. Let vision speak the language of RGB! [2025.05] Patchification Scaling Laws is accepted by ICML 2025. We find that a pixel is worth a token! [2025.02] Two papers about linear attention design are accepted by CVPR 2025! [2024.07] SCLIP is accepted by ECCV 2024. It's an elegant way to extract dense CLIP features without training! [2023.08] Come to Johns Hopkins University and start my PhD life! |
|
|
|
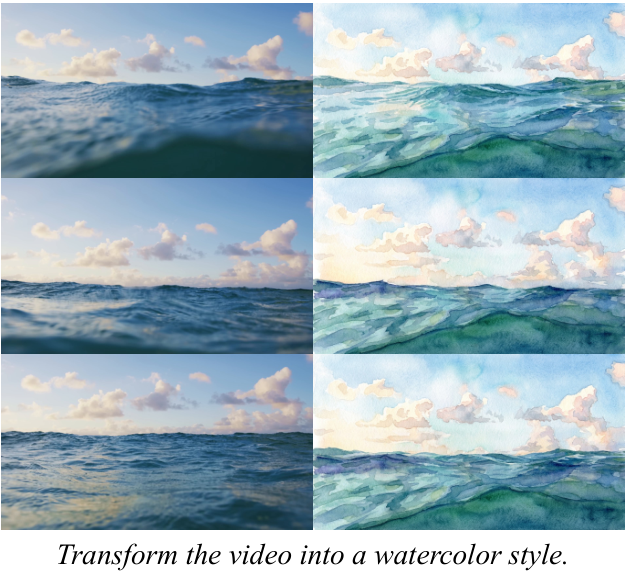
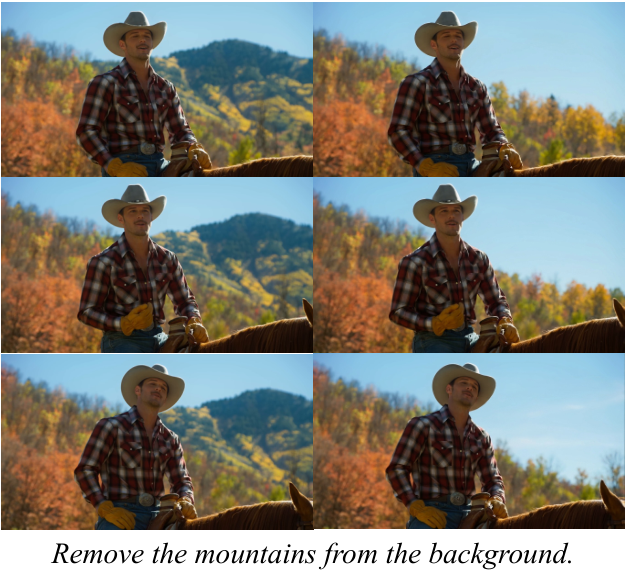
Feng Wang, Zijie Li, Ceyuan Yang, Alan Yuille, Peng Wang NeurIPS 2026 . | arXiv | code We present Anchor-based Video Editing (AVE), which turns a strong image editor into a video editor without training an end-to-end video editing model. The image editor first edits a sparse set of keyframes, and a motion-guided image-to-video diffusion model then propagates the edits across the video with the edited keyframes as fixed anchors. |
|
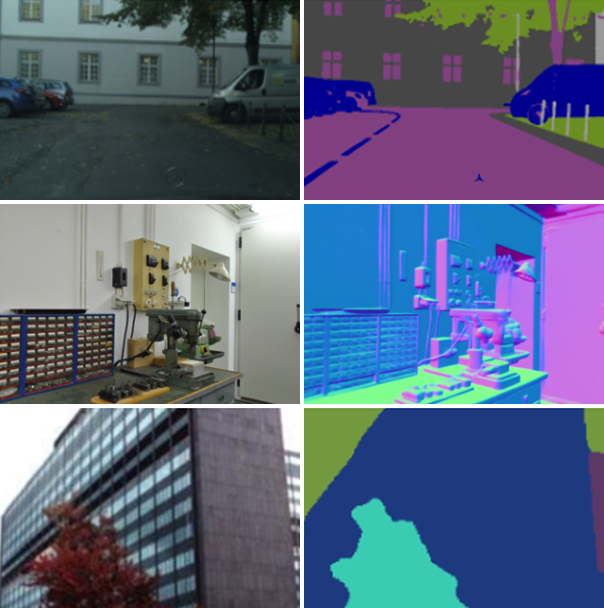
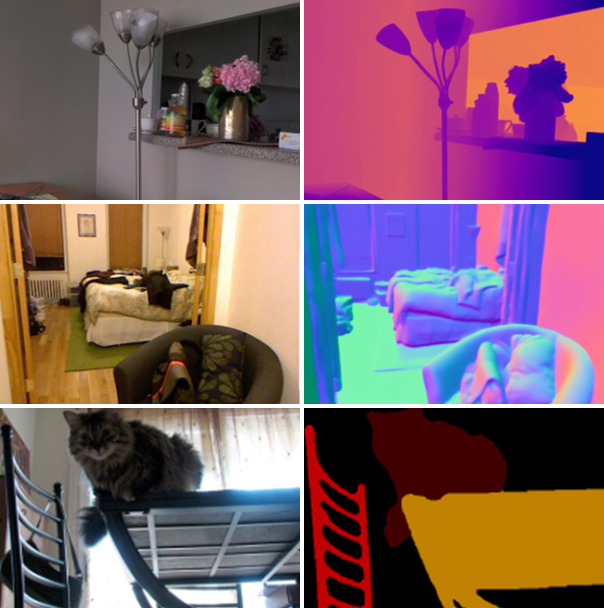
Timing Yang, Jinrui Yang, Xinlong Li, Yuhan Wang, Haoran Li, Yanqing Liu, Guoyizhe Wei, Jixuan Ying, Chen Wei, Rama Chellappa, Yuyin Zhou, Cihang Xie, Alan Yuille, Feng Wang† Work in progress . | arXiv | code We propose RINO (RGB In and RGB Out), which represents diverse visual information such as masks, depth maps and poses as RGB images, and casts general vision tasks as RGB-to-RGB image editing. Built on a generic image editor without task-specific fine-tuning, RINO handles dense understanding tasks and dense-conditioned generation in a zero-shot manner. |
|
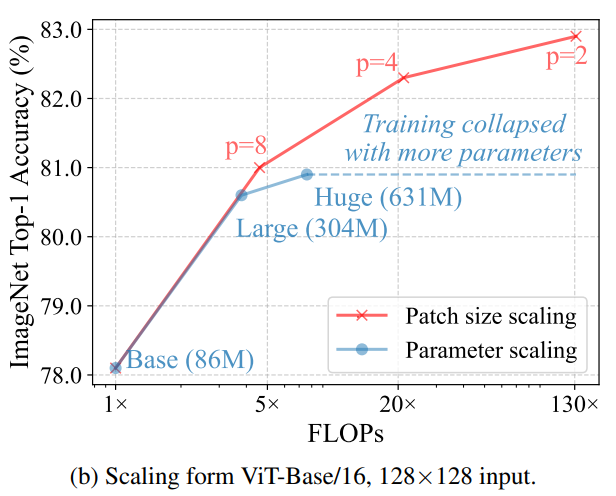
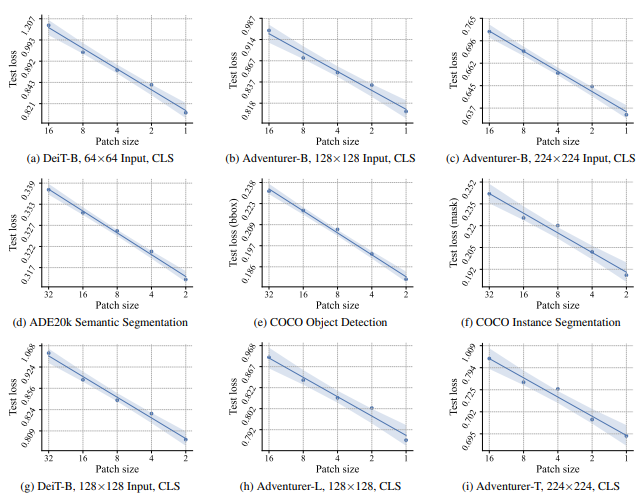
Feng Wang, Yaodong Yu, Wei Shao, Yuyin Zhou, Alan Yuille, Cihang Xie ICML 2025 . | arXiv | code We introduce Patchification Scaling Laws, where we find that the patch size of Vision Transformers and recurrent models can be scaled down to 1x1 with consistently improved predictive performance. We challenge the notion that "an image is worth 256 tokens"---actually it is worth 50,176 and even more. |
|
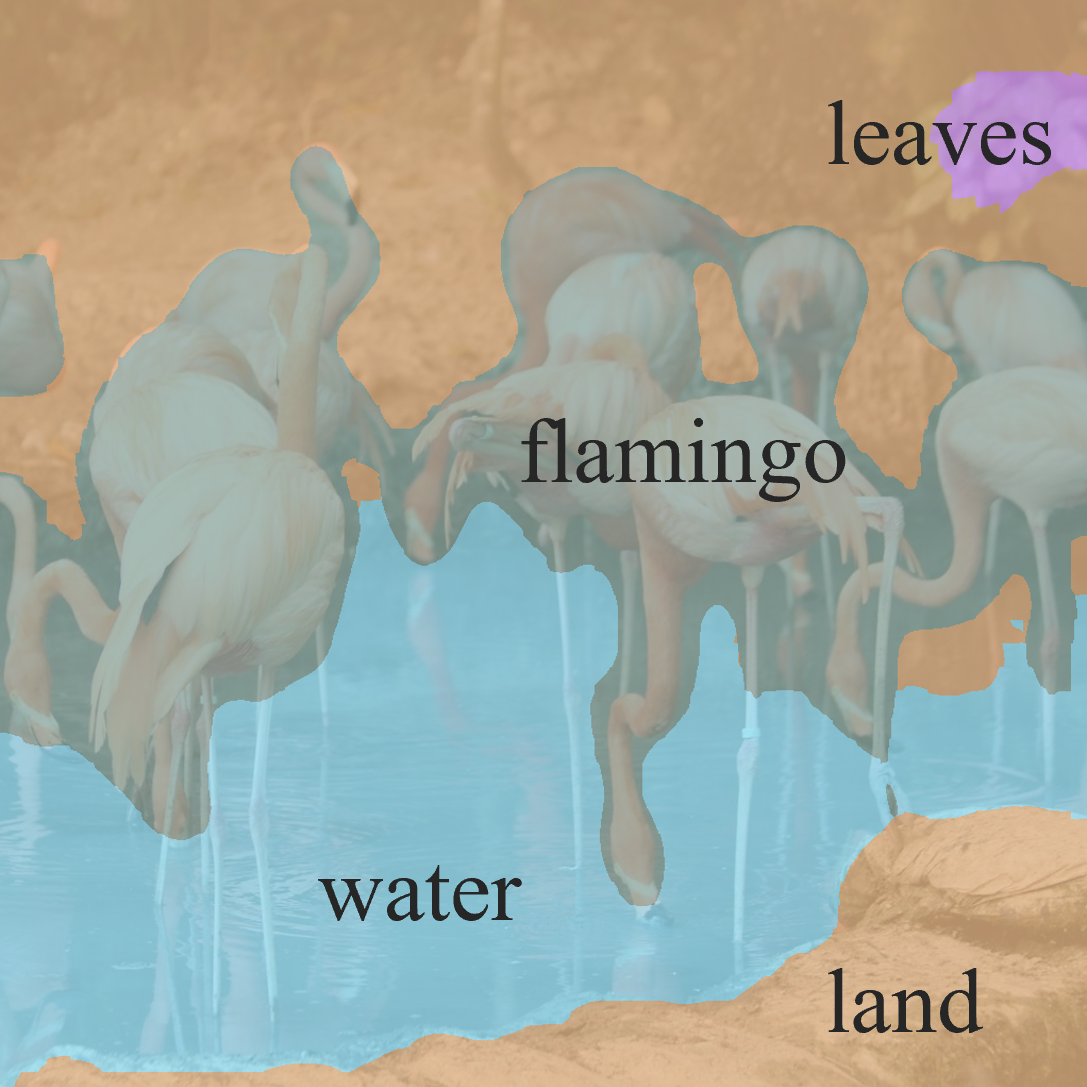
Feng Wang, Jieru Mei, Alan Yuille ECCV 2024 . | arXiv | code We present a zero-shot semantic segmentation model called SCLIP (Segmentation-adapted CLIP model), which leverages our newly proposed correlative self-attention mechanism and allows training-free adaptation to semantic segmentation tasks with CLIP. |
|
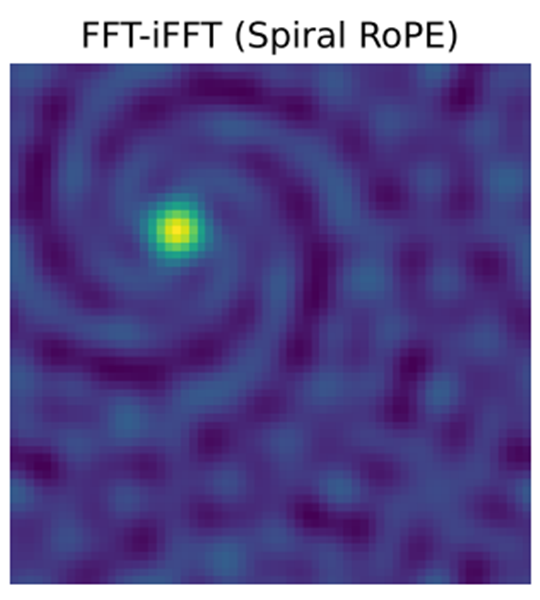
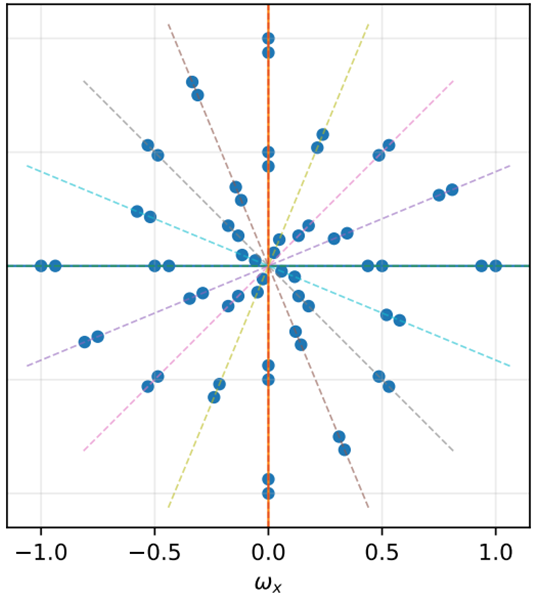
Haoyu Liu, Sucheng Ren, Tingyu Zhu, Peng Wang, Cihang Xie, Alan Yuille, Zeyu Zheng, Feng Wang† ICML 2026 . | arXiv Standard axial 2D RoPE splits positions into horizontal and vertical components, restricting positional encoding to axis-aligned directions. We propose Spiral RoPE, which assigns channel groups to uniformly distributed directions and rotates each group by the projection of the patch position onto its direction, bringing consistent gains on classification, segmentation and generation. |
|
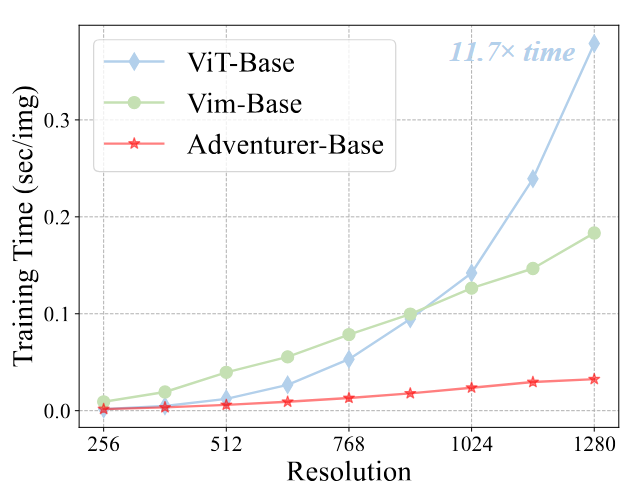
Feng Wang, Timing Yang, Yaodong Yu, Sucheng Ren, Guoyizhe Wei, Angtian Wang, Wei Shao, Yuyin Zhou, Alan Yuille, Cihang Xie, CVPR 2025 . | arXiv | code We present a comprehensive analysis of causal image modeling and introduce the Adventurer series models where we treat images as sequences of patch tokens and employ uni-directional language models to learn visual representations. This modeling paradigm allows us to process images in a recurrent formulation with linear complexity relative to the sequence length, which can effectively address the memory and computation explosion issues posed by high-resolution and fine-grained images. |
|
Feng Wang, Jiahao Wang, Sucheng Ren, Guoyizhe Wei, Jieru Mei, Wei Shao, Yuyin Zhou, Alan Yuille, Cihang Xie, CVPR 2025 . | arXiv | code Similar to Vision Transformers, we identify artifacts also present within the feature maps of Vision Mamba. These artifacts, corresponding to high-norm tokens emerging in low-information background areas of images, appear much more severe in Vision Mamba. |
|
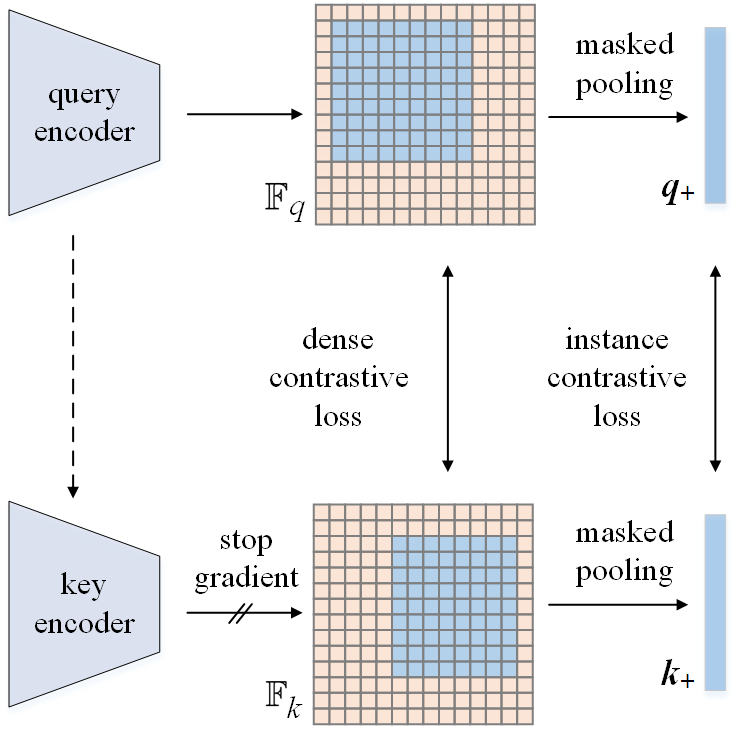
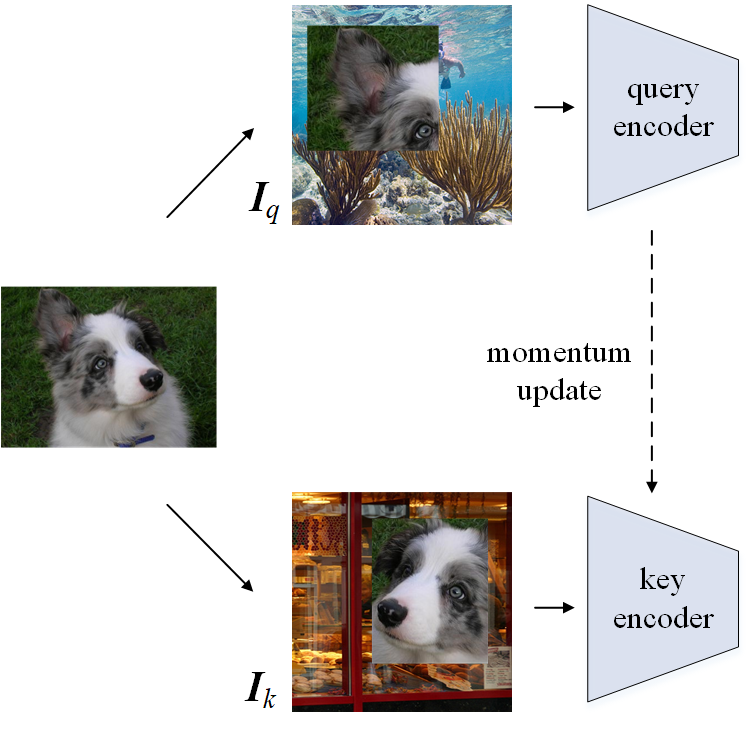
Feng Wang, Huiyu Wang, Chen Wei, Alan Yuille, Wei Shen ECCV , 2022 | arXiv / code We propose a dense (pixel-wise) self-supervised contrastive learning method called CP2, which facilitates both image- and pixel-level representations. We obtain 78.6% mIoU with a ResNet-50 and 79.5% with a ViT-S by finetuning CP2 pretrained models on PASCAL VOC. |
|
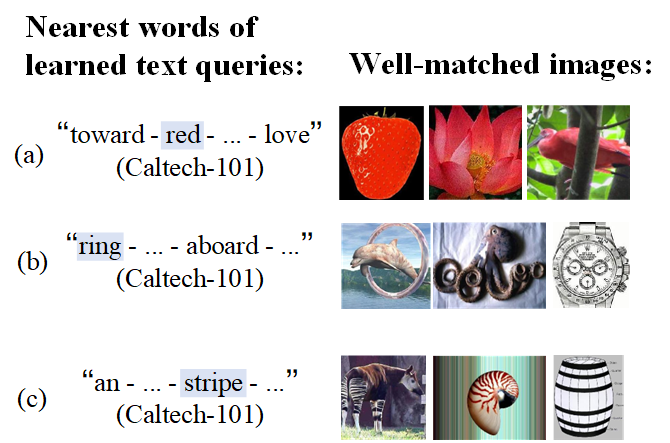
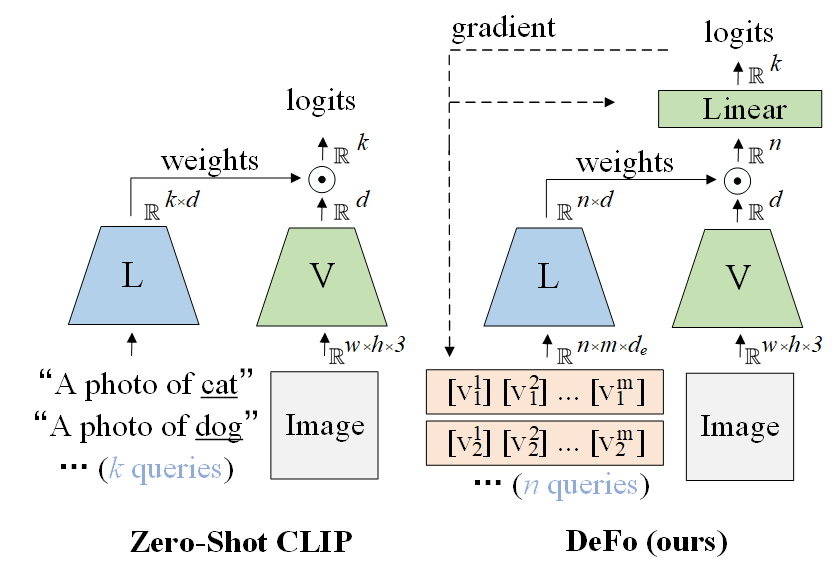
Feng Wang, Manling Li, Xudong Lin, Hairong Lv, Alexander G. Schwing, Heng Ji ICLR , 2023. | arXiv We propose a novel vision-language model called Decomposed Feature Prompting (short as DeFo), which decouples the language inputs from the classes to be inferred, and learns to extract detailed visual features with textual prompts. |
|
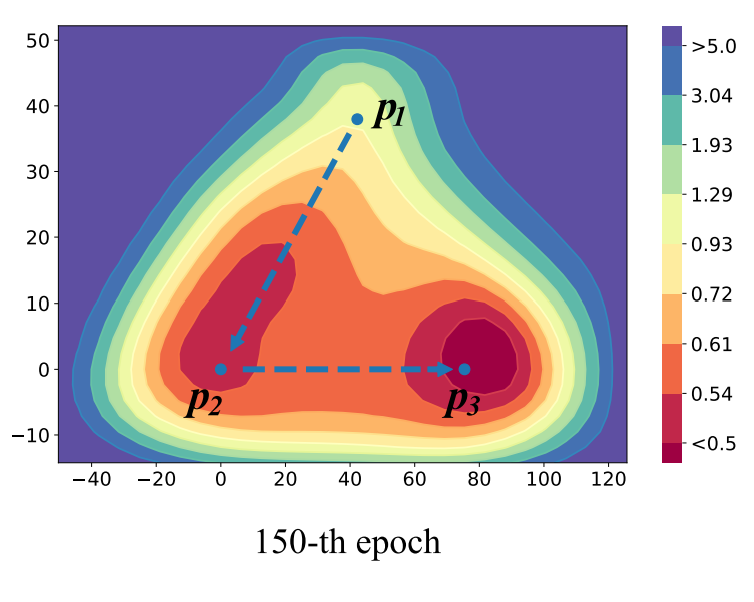
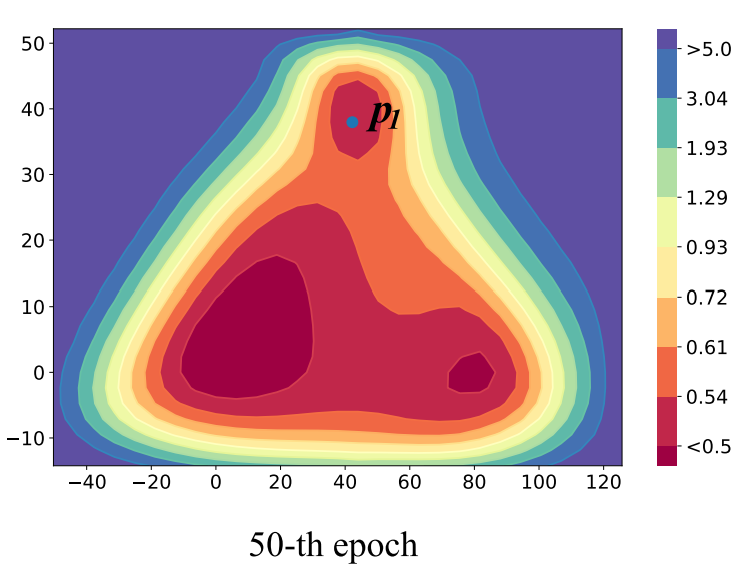
Feng Wang, Guoyizhe Wei, Qiao Liu, Jinxiang Ou, Xian Wei, Hairong Lv NeurIPS , 2021 | arXiv We propose a novel checkpoint ensemble called Checkpoint Boosted Neural Networks (CBNN), where a boosting scheme is utilized to accelerate model convergence and maximize the checkpoint diversity. Our superior performance is supported by a theoretical proof. |
|
Last update: Oct. 2026 Template |